Models & Providers
Dynamo is provider-agnostic. Use any LLM from any provider.
Model capabilities (context window, tool support, reasoning, vision) are auto-detected at runtime via live probes against each provider — no hardcoded model→capability tables. Newly-released models work immediately, and context windows are re-checked on every model switch since providers expand them over time.
Switching Models
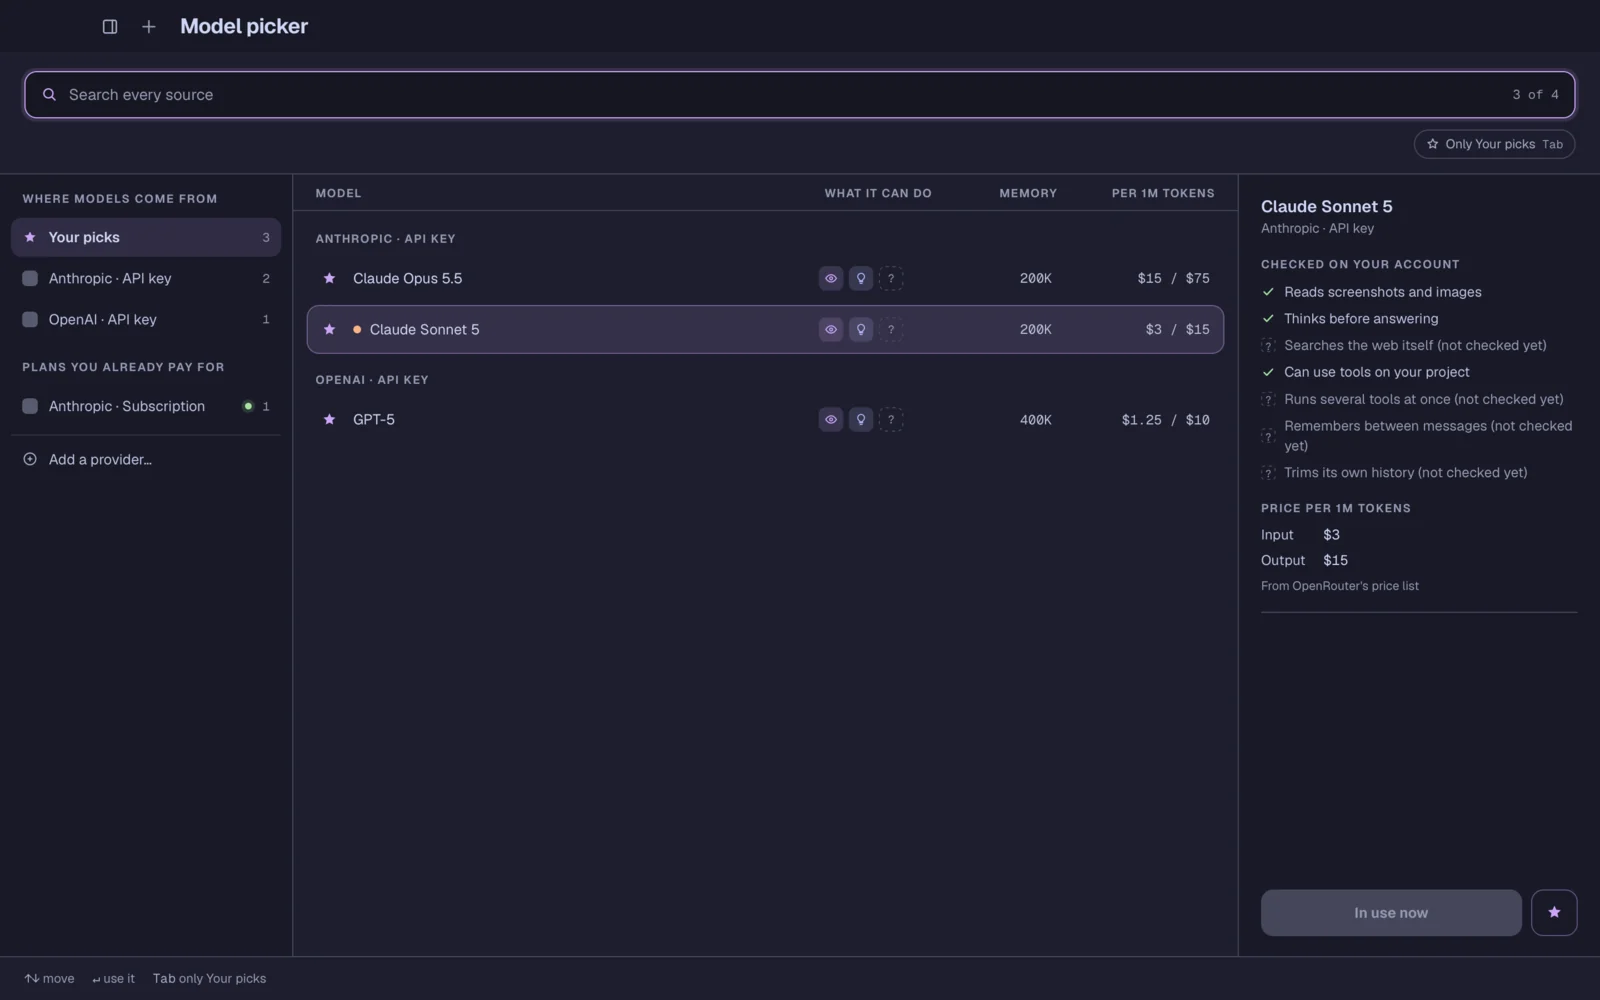
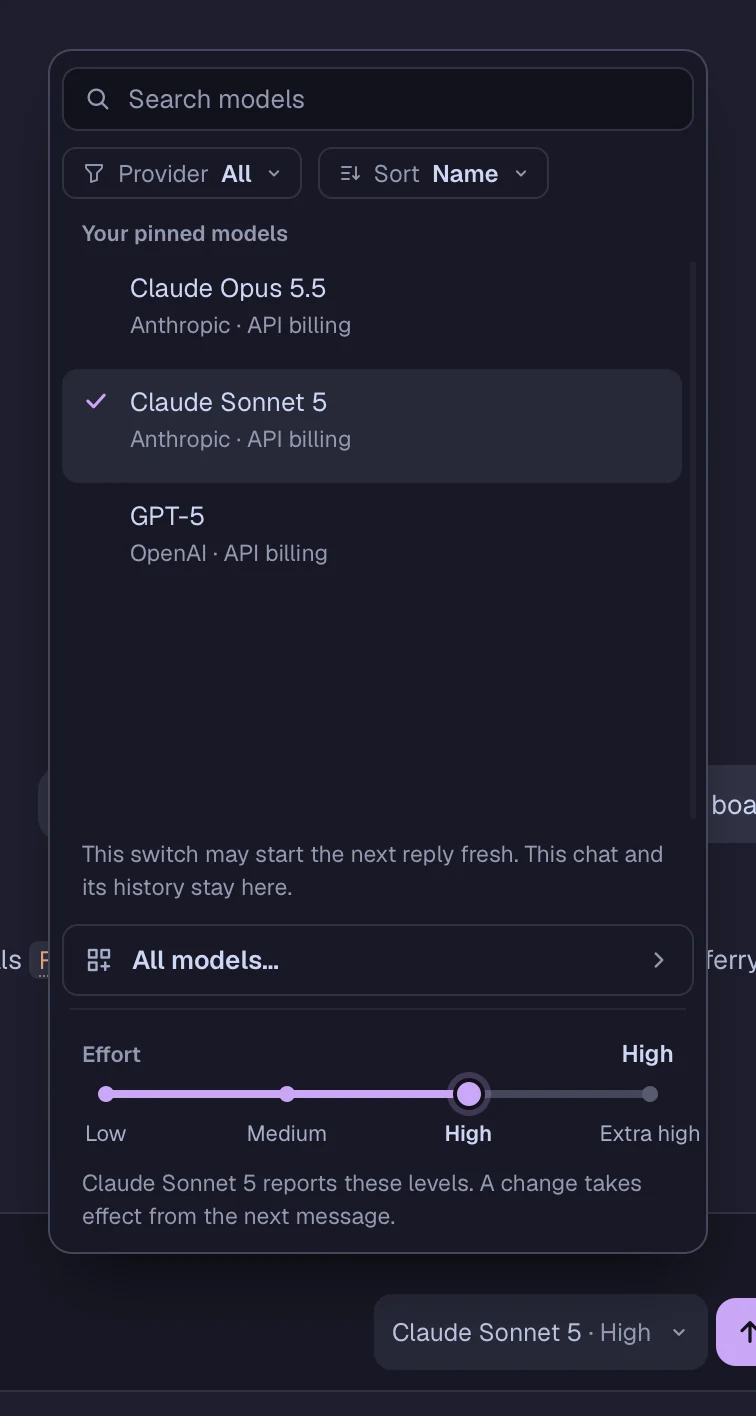
Type /model to open the model picker, or switch directly:
/model              # opens a picker with all available models
/model <alias>      # switch to a model you've named
The picker lists what your configured providers actually offer, so it never goes stale. Today that includes Claude Fable 5.2, Claude Haiku 5.5, Claude Sonnet 5.5 from Anthropic and GPT-6.1 Terra Pro from OpenAI.
Your choice is saved and persists across sessions.
You can also use the full provider/model format: /model anthropic/<model>, /model openai/<model>, /model google/<model>, /model xai/<model>, /model openrouter/<vendor>/<model>, or /model ollama/<model>.
Aliases
Dynamo ships no built-in aliases — a fixed table of model ids goes stale the day a provider ships a new generation. Every alias is yours: open /model, highlight a row on the Active Models tab and press r to name it, or pin a model (pinned models get a generated alias). Aliases set in OpenClaw work too. Your names persist across sessions.
/model                # browse; `r` renames the highlighted row
/model my-fast        # then use your alias anywhere
Anthropic (Claude)
Set ANTHROPIC_API_KEY to use Claude models directly. Anthropic is the recommended provider for Dynamo — best tool use, streaming, and extended thinking support.
/model                        # pick from the live Anthropic list
/model anthropic/<model-id>   # or switch directly
Models like: Claude Fable 5.2, Claude Haiku 5.5, Claude Sonnet 5.5. All Claude models support streaming, tool calling, and extended thinking.
OpenAI (GPT)
Set OPENAI_API_KEY to use GPT models directly. Supports the Chat Completions and Responses APIs, web search, and reasoning models.
/model                     # pick from the live OpenAI list
/model openai/<model-id>   # or switch directly
Models like: GPT-6.1 Terra Pro, GPT-6.1 Terra, GPT-6.1 Sol Pro.
Current GPT models support streaming, tool calling, web search (via the Responses API), and extended thinking.
OpenRouter (200+ Models)
OpenRouter gives you access to 200+ models through a single API key. Set OPENROUTER_API_KEY and use the tabbed model picker to browse and pin models:
/model                                       # Active Models tab, then one tab per provider, then OpenRouter
/model openrouter/<vendor>/<model>           # switch directly
/model my-alias                              # use an alias you named
Use ←/→ to switch tabs. In the OpenRouter tab, type to search. On any provider tab, press Space to pin a model. Pinned models show on the Active Models tab.
Google Gemini
Set GOOGLE_API_KEY to use Gemini models directly:
/model                     # pick from the live Gemini list
/model google/<model-id>   # or switch directly
Models like: Gemini 4 Carbon, Gemini 4 Argon, Gemini 3.8 Flash. Gemini supports streaming, function calling, and extended thinking.
xAI (Grok)
Set XAI_API_KEY to use Grok models directly:
/model                  # pick from the live xAI list
/model xai/<model-id>   # or switch directly
Models like: Grok 4.7, Grok 4.6, Grok 4.5.
Local Models with Ollama
Dynamo works with Ollama for fully local, offline AI:
# Install Ollama and pull a model
ollama pull qwen3:4b-thinking

# Dynamo auto-detects Ollama
dynamo
/model ollama/qwen3:4b-thinking
Local models support tool calling, extended thinking (Qwen3, DeepSeek-R1), and streaming. No API key needed — everything runs on your machine.
Using a CLI subscription
If you already pay for a Claude or Grok subscription, Dynamo can run through that subscription's CLI instead of an API key — no per-token billing on your side. Pick the subscription entry from /model; Dynamo uses the CLI's own sign-in, so make sure you're logged in there first.
Both are experimental, and for different reasons — see Getting Started for the full detail on each.
XAI_API_KEY. Needs the Grok CLI installed and signed in (grok login). If Grok stops answering, open a new Terminal window, type grok update and press Enter, then send your message again.An API key is the path that can't be withdrawn. If you need Dynamo to keep working predictably, add one — the subscription option is a convenience on top, not the foundation.
Custom Providers
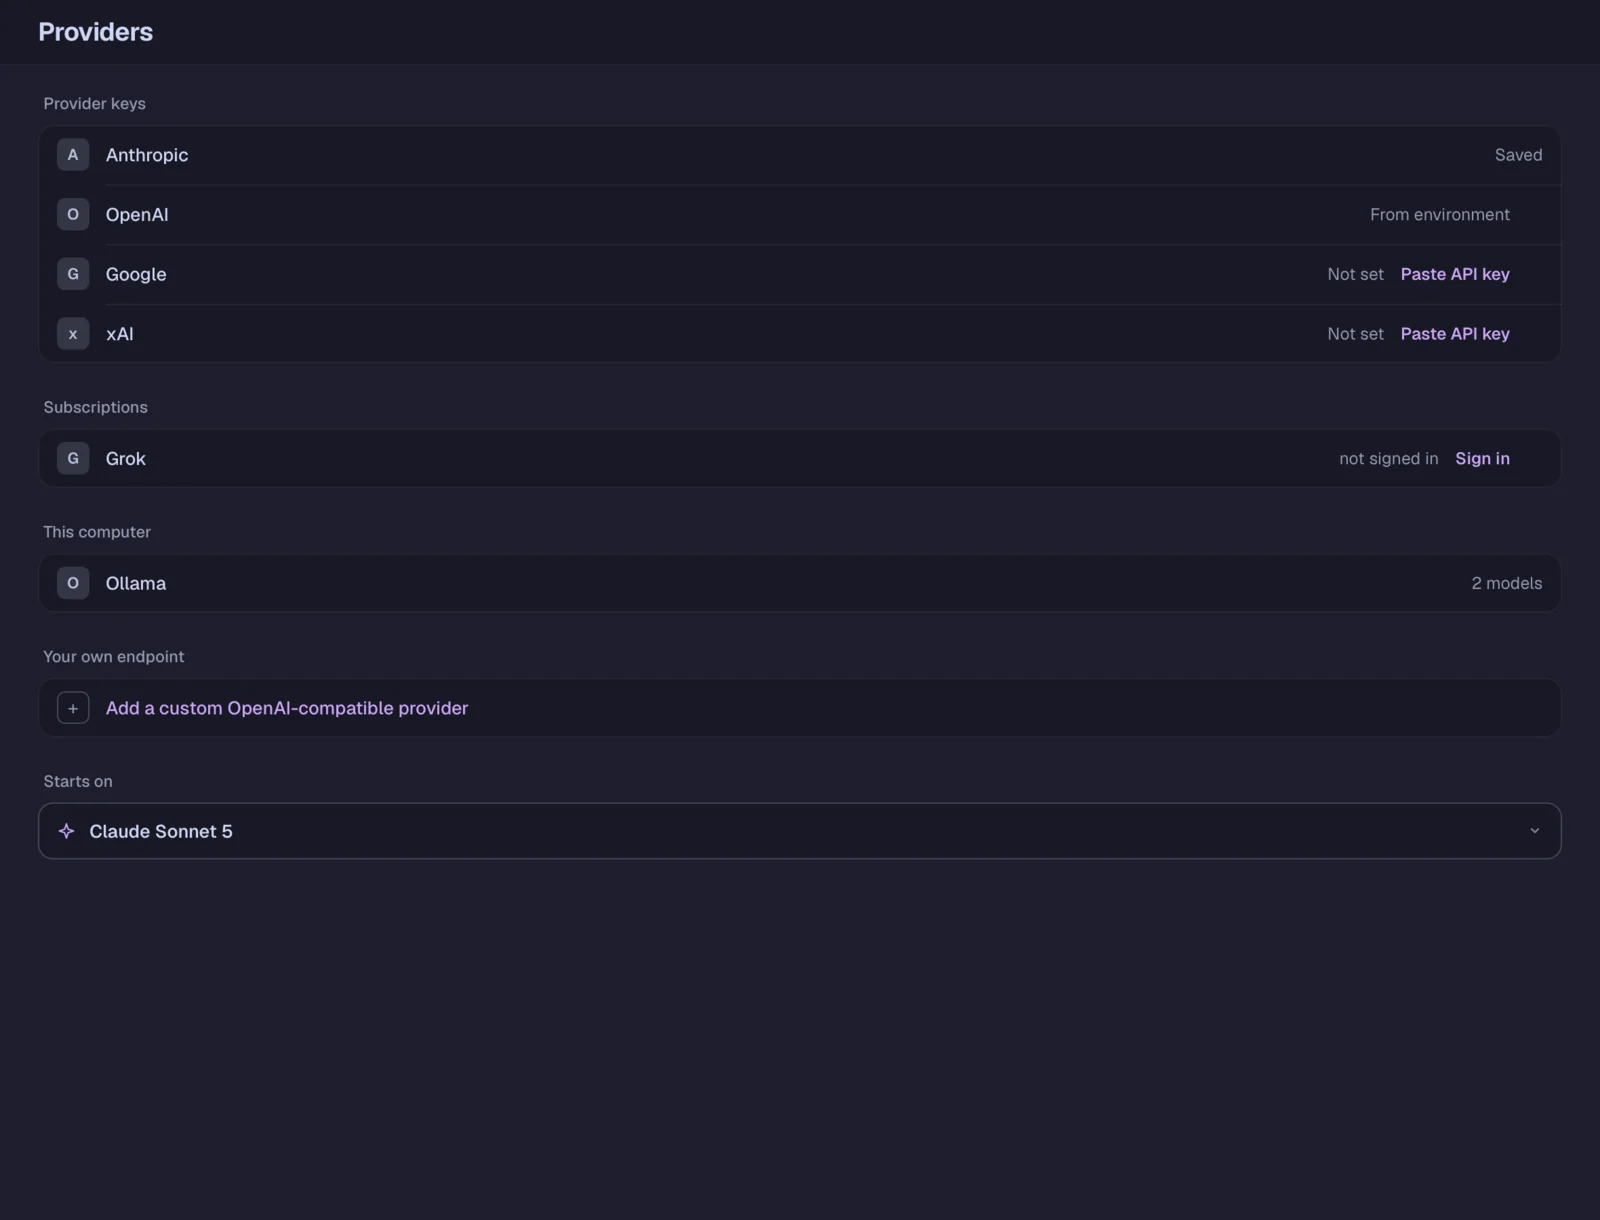
Add any OpenAI-compatible endpoint in dynamo.yaml:
ai:
  providers:
    deepseek:
      type: "openai-compatible"
      base_url: "https://api.deepseek.com/v1"
      api_key_env: "DEEPSEEK_API_KEY"
Then use /model deepseek/deepseek-chat to switch.
Reasoning Levels
Use /effort to control how much the model thinks before responding:
| Level | What it does |
|---|---|
low | Quick responses, minimal reasoning |
medium | Balanced (default) |
high | Extended thinking — model shows its reasoning |
xhigh | Longer thinking than high — the sweet spot for tricky code on the models that offer it |
max | Everything the model has. Slowest, and worth it for a genuinely hard problem |
Not every model offers the top two levels, and each provider handles them its own way:
- OpenAI — Dynamo asks the model which levels it accepts when you switch to it, and sends
highin place ofxhighormaxon a model that doesn't have them. On an OpenAI model you can ask Dynamo whether it hasxhighandmax, and it answers from what it found. - Claude — current models are sent the level itself; older ones get a longer or shorter thinking budget for each level.
- Gemini — each level up to
xhighis a larger thinking budget;maxlets the model decide how long to think. - OpenRouter —
xhighis always sent ashigh, whatever the model. - Ollama —
high,xhighandmaxall simply turn thinking on.
Extended thinking is supported by Claude, GPT (via the Responses API), Gemini, OpenRouter models with reasoning support, and Ollama models like Qwen3 and DeepSeek-R1. The thinking output appears in a dimmed block above the response.
Token Display
After each response, Dynamo shows token usage:
<model> · 348 · 187 · 412 · 12,247 | Glyph | Meaning |
|---|---|
| | Input tokens — fresh tokens not served from cache |
| | Output tokens |
| | Reasoning tokens (reasoning models only — subtracted from output count) |
| | Cached input tokens — prompt content served from cache instead of reprocessed |
In terminals without Nerd Font support, Dynamo falls back to plain Unicode: ↑ ↓ ◇ ✶.
Total prompt size is input + cached. With prompt caching, most of your conversation history is served from cache on each turn — only the new message and tool results count as fresh input tokens.